Data Science Consulting Services That Turn Business Questions Into Predictive Intelligence
Data Engineering & Data Science Services — Turning Raw Data Into Your Most Valuable Asset
Data is everywhere. The organisations winning in 2026 are not the ones with the most of it — they’re the ones who’ve built the infrastructure, intelligence, and governance to turn it into decisions that actually matter. At AI Media Labs, a globally trusted Big Data Analytics Company and full-service data partner, we design, build, and operate the data systems that power your analytics, AI, and business strategy. From AI Data Pipeline Development to advanced Data Science Consulting Services, we help enterprises in every industry unify their data, trust their numbers, and move from reporting to real-time action.
Our Core Data Engineering
&
Data Science Services
AI Data Pipeline Development & ETL/ELT Engineering
Cloud Data Architecture & Migration
Data Science Consulting & Advanced Analytics
Big Data Analytics & Business Intelligence
MLOps and Data Platform Services
Data Governance, Quality & Compliance
Key Challenges In
Data Engineering & Data Science
Data Silos and Poor Data Quality
Legacy System Integration
Scaling Data Infrastructure Efficiently
AI and Data Science Talent Shortage
Data Governance and Regulatory Compliance
Moving from Pilots to Production
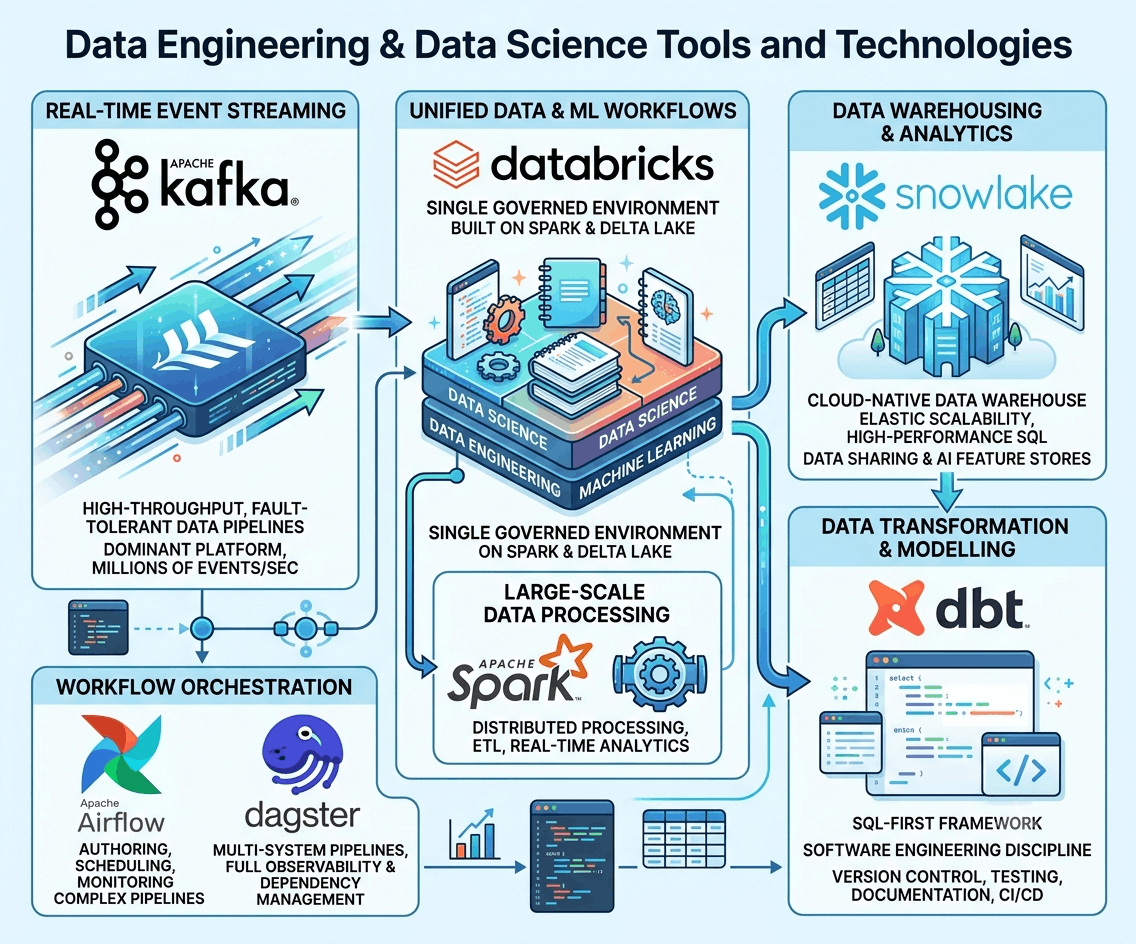
Our Comprehensive Tools and Technologies for Data Engineering & Data Science
Use Cases & Real-World
Data Engineering & Data Science Success Stories
Netflix — 500 Billion Events Processed Daily
Uber — Real-Time Data Driving Operational Efficiency
Airbnb — 20% Increase in Bookings via Data-Driven Pricing
General Electric — Predictive Maintenance at Industrial Scale
Zalando — AI Recommendation Engine Cutting Returns
Enterprise Cloud Optimisation — 25% Cost Reduction in Month One
Why Choose
AI Media Labs for
Data Engineering & Data Science Services?
Reliable Data Engineering Company to Help You Unify and Navigate Digital Data
Most organisations do not have a data shortage. They have a data coherence problem. Customer records exist in five systems that disagree on a customer’s name. Sales numbers differ between the CRM and the finance system. The data warehouse runs a batch job that’s already twelve hours stale by the time the morning report runs. The ML model the data science team spent six months building has never made it into production because no one built the infrastructure to deploy it.
This is the reality AI Media Labs encounters in most enterprise data engagements — and the reality our Data Engineering Services are designed to resolve.
The Data Engineering Market Has Reached a Tipping Point
The global data engineering and big data services market was valued at $105 billion in 2026 and is forecast to reach $213 billion by 2031, with 85% of industry respondents describing data engineering as critically important for business outcomes. The infrastructure for collecting, transforming, and serving data is no longer a back-office function — it is the operational backbone of every AI-enabled enterprise.
The era of proof-of-concept data projects is ending. Organisations are now asking a harder question: why aren’t these investments delivering measurable returns? The answer, almost universally, is engineering quality — not the technology chosen, but the rigour with which it’s designed, built, and maintained.
What Our Data Engineering Services Actually Deliver
AI Media Labs begins every engagement with a data infrastructure audit — a structured examination of your current architecture, data flows, tooling, quality, and governance posture. This audit produces a prioritised picture of where data reliability breaks down, where bottlenecks occur, and where the highest-ROI engineering investments lie. Only after this audit do we move to architecture — problem-first, technology second.
AI Data Pipeline Development: The Foundation of Everything
Every downstream data product — every analytics dashboard, every machine learning model, every operational report — is only as reliable as the data pipeline feeding it. Unreliable pipelines produce unreliable outputs. Unreliable outputs destroy trust in data, and once that trust is gone, the organisation reverts to spreadsheets and gut instinct.
Our AI Data Pipeline Development practice builds pipelines engineered for production: idempotent, resumable, observable, and schema-aware. We implement data quality checks at ingestion, transformation, and serving layers — catching anomalies before they propagate to dashboards and models that business decisions depend on. Every pipeline is instrumented with monitoring that alerts when volumes deviate, when errors spike, or when SLA windows are at risk.
Big Data Analytics Company: From Data to Decisions
Data volume is not the challenge. The challenge is building the analytical infrastructure that allows the right people to access the right data at the right time — without waiting hours for dashboards to refresh, without data analysts spending 80% of their time cleaning data rather than generating insight.
Our Big Data Analytics Company practice builds analytics platforms that balance self-service accessibility with governance rigour. Business users explore data in familiar BI tools. Data scientists access clean, governed datasets for modelling. Leadership trusts the numbers they see in executive dashboards because they come from a single governed source of truth — not ten spreadsheets that calculate revenue differently.
MLOps and Data Platform Services: Industrialising Your AI
The hardest part of machine learning is not building models — it’s keeping them working in production. Models degrade as data distributions shift. Training pipelines fail silently. Performance goes unmonitored until a stale prediction produces a costly outcome.
Our MLOps and Data Platform Services practice addresses this systematically — with model training pipelines built on experiment tracking and version control, automated CI/CD deployment with pre-production validation, drift detection and retraining triggers, and feature stores that make engineered features reusable across projects. The result is AI that performs reliably in production, not just in the lab.
Data Science Consulting Services: Intelligence That Drives Action
Our Data Science Consulting Services focus on identifying the specific, repeated decisions in your organisation where better models produce materially better outcomes — then building precisely those capabilities. We translate business questions into modelling problems, source and prepare the required data, train and validate the appropriate algorithms, and deploy predictions into operational workflows where they’ll actually influence decisions.
Frequently Asked Questions
Data engineering is the practice of designing and building the systems that collect, transform, store, and serve data reliably at scale. Without it, data sits in siloed, inconsistent systems that analysts cannot trust, AI models cannot learn from, and business leaders cannot act on. Data engineering is the foundation that every data-driven and AI-enabled business capability is built on.
Data engineering builds and maintains the infrastructure that makes data available, reliable, and accessible. Data science uses that infrastructure to extract insight — building predictive models, statistical analyses, and AI applications. The two disciplines are deeply interdependent: data science without data engineering produces models that never make it to production; data engineering without data science produces infrastructure with no analytical intelligence on top.
An AI data pipeline extends traditional ETL by incorporating feature engineering, model serving infrastructure, prediction logging, and feedback loops that enable machine learning systems to be trained and updated continuously from live data. Where traditional ETL moves data from A to B, an AI data pipeline makes that data usable as model input and captures model outputs for monitoring and retraining.
MLOps (Machine Learning Operations) applies DevOps principles to machine learning — covering model training automation, version control, CI/CD deployment, production monitoring, and automated retraining. Data Platform Services provide the governed, scalable infrastructure on which both analytics and ML workloads run. Together, they industrialise AI from experimental prototype to reliable production system.
A foundational cloud data platform with core pipelines, a data warehouse, and basic BI capability typically takes 8–16 weeks to deliver for an organisation with reasonable data readiness. A comprehensive enterprise data platform with governance, ML infrastructure, and advanced analytics typically takes 4–9 months. AI Media Labs provides a detailed phased roadmap at the start of every engagement.
We implement multi-layer data quality: schema validation and volume checks at ingestion, transformation-layer tests using dbt’s built-in testing framework, and serving-layer anomaly detection that compares metric values against statistical baselines. Every quality failure generates an alert before it reaches downstream consumers — preventing bad data from reaching the dashboards and models that business decisions depend on.
We serve financial services, retail and e-commerce, healthcare, manufacturing, logistics, media, telecommunications, and professional services — with domain-adapted data models, compliance frameworks, and analytical use cases tailored to the specific data landscape and regulatory requirements of each sector.